mirror of
https://github.com/EDeev/converterbot.git
synced 2026-10-08 04:59:32 +03:00
Compare commits
No commits in common. "5f9ef626f1f1ee06949dcb56a7f5208ebd7a1bf6" and "af19aa999f2f2e89709aebbcb38012bfb62c3666" have entirely different histories.
5f9ef626f1
...
af19aa999f
23 changed files with 496 additions and 951 deletions
|
|
@ -1,2 +0,0 @@
|
||||||
# Токен бота от @BotFather
|
|
||||||
BOT_TOKEN=123456:your-token
|
|
||||||
2
.gitattributes
vendored
2
.gitattributes
vendored
|
|
@ -1,2 +0,0 @@
|
||||||
* text=auto eol=lf
|
|
||||||
*.docx binary
|
|
||||||
27
.github/workflows/ci.yml
vendored
27
.github/workflows/ci.yml
vendored
|
|
@ -1,27 +0,0 @@
|
||||||
name: CI
|
|
||||||
|
|
||||||
on:
|
|
||||||
push:
|
|
||||||
branches: [main]
|
|
||||||
pull_request:
|
|
||||||
|
|
||||||
jobs:
|
|
||||||
test:
|
|
||||||
runs-on: ubuntu-latest
|
|
||||||
strategy:
|
|
||||||
matrix:
|
|
||||||
python-version: ["3.9", "3.12", "3.13"]
|
|
||||||
steps:
|
|
||||||
- uses: actions/checkout@v4
|
|
||||||
- uses: actions/setup-python@v5
|
|
||||||
with:
|
|
||||||
python-version: ${{ matrix.python-version }}
|
|
||||||
- run: pip install pytest==8.4.2 ruff==0.14.0 build python-docx
|
|
||||||
- run: ruff check --select E9,F,B .
|
|
||||||
- name: Тесты пакета md2gost
|
|
||||||
run: pytest -q tests/test_md2gost.py
|
|
||||||
- name: Тесты бота
|
|
||||||
if: matrix.python-version != '3.9'
|
|
||||||
run: pip install -r requirements.txt && pytest -q tests/test_bot_helpers.py
|
|
||||||
- name: Сборка пакета
|
|
||||||
run: python -m build && pip install dist/*.whl && md2gost --version
|
|
||||||
61
.github/workflows/release.yml
vendored
61
.github/workflows/release.yml
vendored
|
|
@ -1,61 +0,0 @@
|
||||||
name: Release
|
|
||||||
|
|
||||||
on:
|
|
||||||
push:
|
|
||||||
tags: ["v*"]
|
|
||||||
|
|
||||||
jobs:
|
|
||||||
pypi:
|
|
||||||
runs-on: ubuntu-latest
|
|
||||||
permissions:
|
|
||||||
contents: write
|
|
||||||
steps:
|
|
||||||
- uses: actions/checkout@v4
|
|
||||||
- uses: actions/setup-python@v5
|
|
||||||
with:
|
|
||||||
python-version: "3.12"
|
|
||||||
- run: pip install build
|
|
||||||
- run: python -m build
|
|
||||||
- name: Публикация md2gost на PyPI
|
|
||||||
uses: pypa/gh-action-pypi-publish@release/v1
|
|
||||||
with:
|
|
||||||
password: ${{ secrets.PYPI_API_TOKEN }}
|
|
||||||
- name: Пакет в релиз GitHub
|
|
||||||
env:
|
|
||||||
GH_TOKEN: ${{ github.token }}
|
|
||||||
run: gh release upload "$GITHUB_REF_NAME" dist/* --clobber || true
|
|
||||||
|
|
||||||
image:
|
|
||||||
runs-on: ubuntu-latest
|
|
||||||
permissions:
|
|
||||||
contents: read
|
|
||||||
packages: write
|
|
||||||
steps:
|
|
||||||
- uses: actions/checkout@v4
|
|
||||||
- uses: docker/setup-buildx-action@v3
|
|
||||||
- uses: docker/login-action@v3
|
|
||||||
with:
|
|
||||||
registry: ghcr.io
|
|
||||||
username: ${{ github.actor }}
|
|
||||||
password: ${{ secrets.GITHUB_TOKEN }}
|
|
||||||
- uses: docker/login-action@v3
|
|
||||||
with:
|
|
||||||
registry: dcr.deev.su
|
|
||||||
username: ${{ secrets.ZOT_USERNAME }}
|
|
||||||
password: ${{ secrets.ZOT_PASSWORD }}
|
|
||||||
- id: meta
|
|
||||||
uses: docker/metadata-action@v5
|
|
||||||
with:
|
|
||||||
images: |
|
|
||||||
ghcr.io/edeev/my_converterbot
|
|
||||||
dcr.deev.su/edeev/my_converterbot
|
|
||||||
tags: |
|
|
||||||
type=semver,pattern={{version}}
|
|
||||||
type=semver,pattern={{major}}.{{minor}}
|
|
||||||
type=raw,value=latest
|
|
||||||
- uses: docker/build-push-action@v6
|
|
||||||
with:
|
|
||||||
context: .
|
|
||||||
push: true
|
|
||||||
tags: ${{ steps.meta.outputs.tags }}
|
|
||||||
labels: ${{ steps.meta.outputs.labels }}
|
|
||||||
7
.gitignore
vendored
7
.gitignore
vendored
|
|
@ -1,7 +0,0 @@
|
||||||
.env
|
|
||||||
__pycache__/
|
|
||||||
*.pyc
|
|
||||||
.pytest_cache/
|
|
||||||
dist/
|
|
||||||
build/
|
|
||||||
*.egg-info/
|
|
||||||
15
Dockerfile
15
Dockerfile
|
|
@ -1,15 +0,0 @@
|
||||||
FROM python:3.12-slim
|
|
||||||
|
|
||||||
ENV PYTHONDONTWRITEBYTECODE=1 \
|
|
||||||
PYTHONUNBUFFERED=1
|
|
||||||
|
|
||||||
WORKDIR /app
|
|
||||||
COPY requirements.txt .
|
|
||||||
RUN pip install --no-cache-dir -r requirements.txt
|
|
||||||
|
|
||||||
COPY bot.py rep_to_txt.py ./
|
|
||||||
COPY md2gost/ md2gost/
|
|
||||||
RUN useradd --create-home --uid 1000 app && chown -R app:app /app
|
|
||||||
USER app
|
|
||||||
|
|
||||||
CMD ["python", "bot.py"]
|
|
||||||
21
LICENSE
21
LICENSE
|
|
@ -1,21 +0,0 @@
|
||||||
MIT License
|
|
||||||
|
|
||||||
Copyright (c) 2025 Egor Deev
|
|
||||||
|
|
||||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
||||||
of this software and associated documentation files (the "Software"), to deal
|
|
||||||
in the Software without restriction, including without limitation the rights
|
|
||||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
||||||
copies of the Software, and to permit persons to whom the Software is
|
|
||||||
furnished to do so, subject to the following conditions:
|
|
||||||
|
|
||||||
The above copyright notice and this permission notice shall be included in all
|
|
||||||
copies or substantial portions of the Software.
|
|
||||||
|
|
||||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
||||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
||||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
||||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
||||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
||||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
||||||
SOFTWARE.
|
|
||||||
92
README.en.md
92
README.en.md
|
|
@ -1,92 +0,0 @@
|
||||||
# My Converter Bot · md2gost
|
|
||||||
|
|
||||||
[Русский](https://github.com/EDeev/my_converterbot/blob/main/README.md) · **English**
|
|
||||||
|
|
||||||
[](https://github.com/EDeev/my_converterbot/actions/workflows/ci.yml)
|
|
||||||
[](https://pypi.org/project/md2gost/)
|
|
||||||
[](https://pypi.org/project/md2gost/)
|
|
||||||
[](https://github.com/EDeev/my_converterbot/blob/main/LICENSE)
|
|
||||||
|
|
||||||
A Markdown to DOCX converter that follows GOST 7.32-2017 (the Russian standard for research and student
|
|
||||||
reports), plus a Telegram bot for study routine: send a `.md` and get a report ready to submit, send a
|
|
||||||
project `.zip` and get a `.txt` with the folder tree and file contents. The converter is installable on its
|
|
||||||
own as the `md2gost` package on PyPI. The bot speaks Russian.
|
|
||||||
|
|
||||||
**Status:** personal project, maintained · bot [@my_convbot](https://t.me/my_convbot) ·
|
|
||||||
package [md2gost](https://pypi.org/project/md2gost/)
|
|
||||||
|
|
||||||
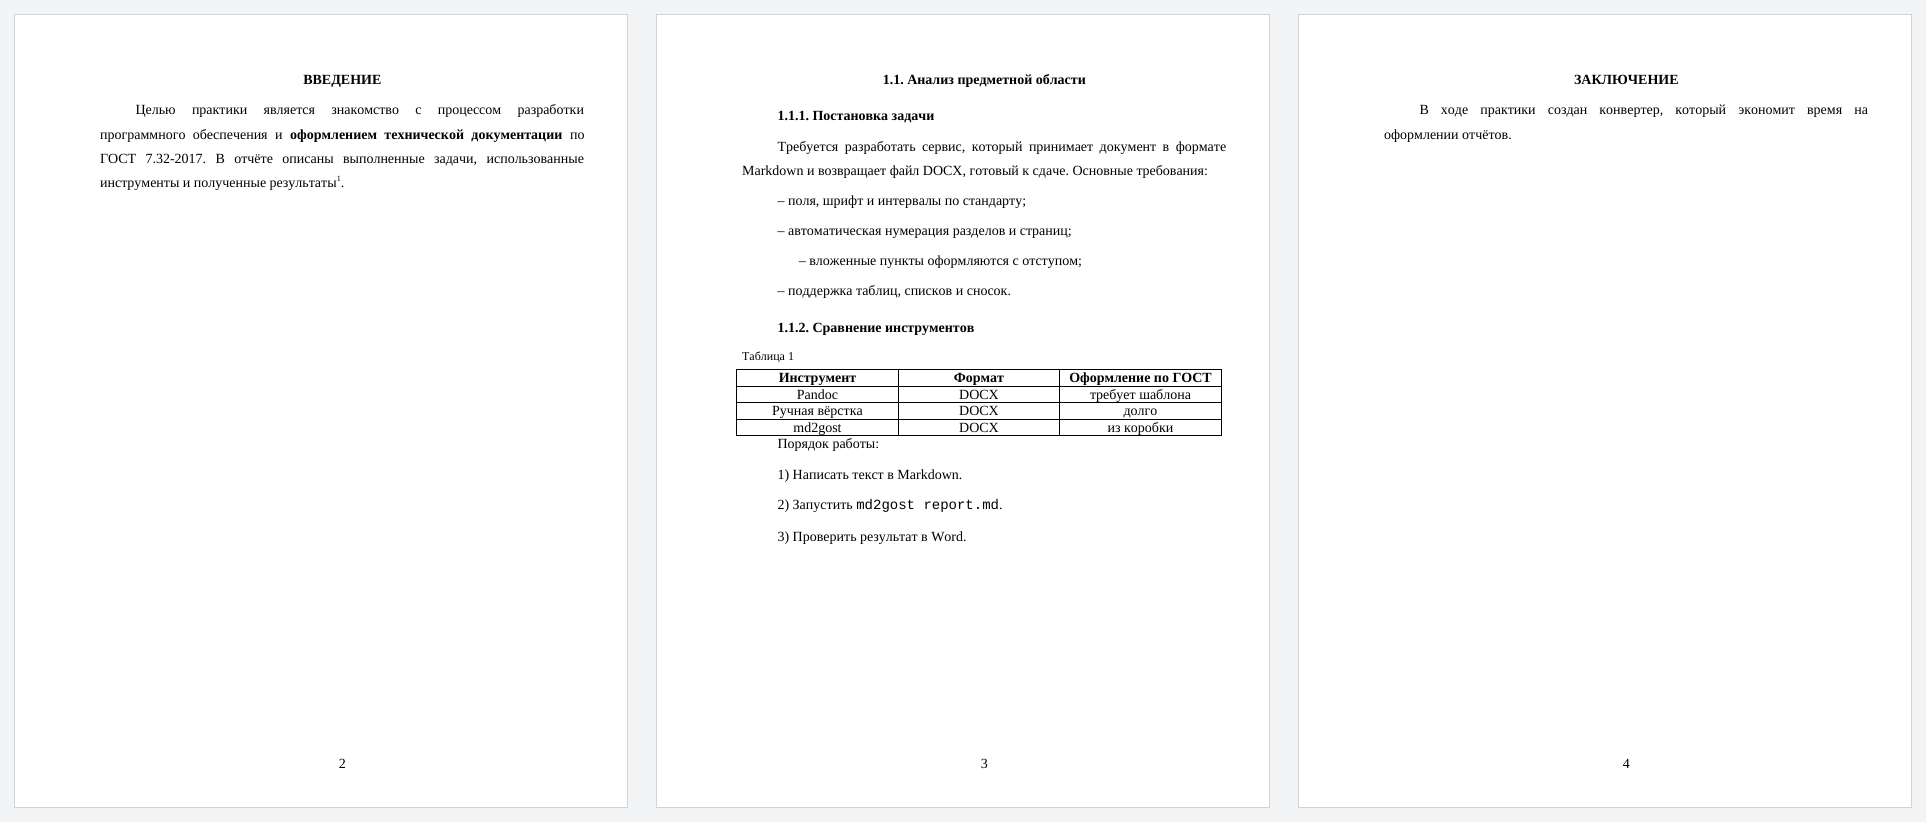
|
|
||||||
|
|
||||||
**Stack:** Python 3.9+ · python-docx · aiogram 3 · Docker
|
|
||||||
|
|
||||||
## md2gost — Markdown → DOCX per GOST
|
|
||||||
|
|
||||||
```bash
|
|
||||||
pip install md2gost
|
|
||||||
md2gost report.md # writes report.docx next to it
|
|
||||||
md2gost report.md -o out.docx --no-heading-numbers
|
|
||||||
```
|
|
||||||
|
|
||||||
What it does to the document:
|
|
||||||
|
|
||||||
- margins: left 30 mm, right 15, top and bottom 20; Times New Roman 14 pt, 1.5 line spacing, 1.25 cm first-line indent, justified text
|
|
||||||
- page numbers at the bottom center, none on the title page
|
|
||||||
- section numbering `1.`, `1.1.`, `1.1.1.`; structural elements ("Введение", "Заключение", "Список
|
|
||||||
литературы" and others) unnumbered, uppercase, centered
|
|
||||||
- a page break before every second-level section
|
|
||||||
- bulleted lists with dashes and nesting, numbered lists as `1)` with numbering restarted per list
|
|
||||||
- tables with a "Таблица N" caption on the top left, code blocks and inline code in a monospace font,
|
|
||||||
quotes, footnotes `[^1]`, bold and italic
|
|
||||||
|
|
||||||
Command-line options: `--font`, `--size`, `--spacing`, `--no-heading-numbers`, `--no-page-numbers`,
|
|
||||||
`--number-title-page`. From Python:
|
|
||||||
|
|
||||||
```python
|
|
||||||
from md2gost import DocumentSettings, MarkdownToDocxConverter
|
|
||||||
|
|
||||||
settings = DocumentSettings()
|
|
||||||
settings.auto_numbering_headings = True
|
|
||||||
MarkdownToDocxConverter(settings).convert("report.md", "report.docx")
|
|
||||||
```
|
|
||||||
|
|
||||||
The Markdown parser is custom and line-based: nested tables and lists inside tables are not supported.
|
|
||||||
|
|
||||||
## The bot
|
|
||||||
|
|
||||||
| Send | Get |
|
|
||||||
|---|---|
|
|
||||||
| `.md` | a GOST-formatted `.docx` (the same md2gost, with heading numbers) |
|
|
||||||
| project `.zip` | a `.txt`: folder tree and contents of text files with line numbers, handy for an LLM or a report appendix |
|
|
||||||
|
|
||||||
Files up to 20 MB. Archives are checked before extraction: at most 5000 files and 200 MB unpacked. Service
|
|
||||||
folders (`.git`, `node_modules`, `__pycache__`, `build`…) and binary files are skipped. Conversion runs in
|
|
||||||
a separate thread, so the bot never freezes on big files.
|
|
||||||
|
|
||||||
```bash
|
|
||||||
git clone https://github.com/EDeev/my_converterbot.git && cd my_converterbot
|
|
||||||
cp .env.example .env # BOT_TOKEN from @BotFather
|
|
||||||
docker compose up -d
|
|
||||||
```
|
|
||||||
|
|
||||||
Prebuilt image: `docker pull ghcr.io/edeev/my_converterbot` or `docker pull dcr.deev.su/edeev/my_converterbot`.
|
|
||||||
Without Docker: `pip install -r requirements.txt`, then `BOT_TOKEN=… python bot.py`.
|
|
||||||
|
|
||||||
`rep_to_txt.py` also works on its own: `python rep_to_txt.py path/to/project`.
|
|
||||||
|
|
||||||
## Development
|
|
||||||
|
|
||||||
```bash
|
|
||||||
pip install -r requirements-dev.txt
|
|
||||||
ruff check --select E9,F,B . && pytest
|
|
||||||
```
|
|
||||||
|
|
||||||
CI tests the package on Python 3.9, 3.12 and 3.13 and builds it. On `v*` tags the package is published to
|
|
||||||
PyPI and the bot's Docker image to GitHub Packages and `dcr.deev.su`.
|
|
||||||
|
|
||||||
## License
|
|
||||||
|
|
||||||
MIT — see [LICENSE](https://github.com/EDeev/my_converterbot/blob/main/LICENSE).
|
|
||||||
|
|
||||||
## Author
|
|
||||||
|
|
||||||
**Egor Deev** — [GitHub](https://github.com/EDeev) · [Telegram](https://t.me/DeevEgor) · [egor@deev.space](mailto:egor@deev.space)
|
|
||||||
223
README.md
223
README.md
|
|
@ -1,108 +1,171 @@
|
||||||
# My Converter Bot · md2gost
|
# 📄 My Converter Bot
|
||||||
|
|
||||||
**Русский** · [English](README.en.md)
|
[](https://www.python.org/)
|
||||||
|
[](https://docs.aiogram.dev/)
|
||||||
|
[](LICENSE)
|
||||||
|
|
||||||
[](https://github.com/EDeev/my_converterbot/actions/workflows/ci.yml)
|
Телеграм-бот для автоматизированной конвертации документов с поддержкой форматирования по ГОСТ 7.32-2017 и анализа структуры проектов.
|
||||||
[](https://pypi.org/project/md2gost/)
|
|
||||||
[](https://pypi.org/project/md2gost/)
|
|
||||||
[](LICENSE)
|
|
||||||
|
|
||||||
Конвертер Markdown в DOCX по ГОСТ 7.32-2017 и Telegram-бот для учебной рутины: присылаешь `.md` —
|
## 🎯 Функциональные возможности
|
||||||
получаешь отчёт, готовый к сдаче, присылаешь `.zip` с проектом — получаешь `.txt` с деревом папок и
|
|
||||||
содержимым файлов. Конвертер ставится отдельно, пакетом `md2gost` с PyPI.
|
|
||||||
|
|
||||||
**Статус:** личный проект, поддерживается · бот [@my_convbot](https://t.me/my_convbot) ·
|
### Конвертация Markdown → DOCX
|
||||||
пакет [md2gost](https://pypi.org/project/md2gost/)
|
- **Полная поддержка ГОСТ 7.32-2017**: автоматическое форматирование научно-технической документации
|
||||||
|
- **Интеллектуальная обработка синтаксиса**: заголовки, списки, таблицы, блоки кода
|
||||||
|
- **Автоматическая нумерация**: иерархическая нумерация разделов (1.1.1, 1.1.2)
|
||||||
|
- **Управление сносками**: интеграция footnotes с автоматическим форматированием
|
||||||
|
- **Настраиваемая типографика**: Times New Roman 14pt, межстрочный интервал 1.5
|
||||||
|
|
||||||

|
### Анализ архивов → TXT
|
||||||
|
- **Древовидная визуализация**: полная структура проекта с UTF-8 оформлением
|
||||||
|
- **Извлечение содержимого**: автоматический экспорт кода из всех текстовых файлов
|
||||||
|
- **Интеллектуальная фильтрация**: игнорирование служебных директорий (node_modules, __pycache__)
|
||||||
|
- **Обработка бинарных файлов**: детектирование и генерация placeholder для медиа
|
||||||
|
|
||||||
**Стек:** Python 3.9+ · python-docx · aiogram 3 · Docker
|
## 🔧 Технологический стек
|
||||||
|
|
||||||
## md2gost — Markdown → DOCX по ГОСТ
|
| Компонент | Технология | Назначение |
|
||||||
|
|-----------|------------|------------|
|
||||||
|
| **Bot Framework** | aiogram 3.x | Асинхронная обработка Telegram API |
|
||||||
|
| **Document Processing** | python-docx | Генерация DOCX с программным управлением стилями |
|
||||||
|
| **Parsing Engine** | re (regex) | Парсинг Markdown синтаксиса |
|
||||||
|
| **Archive Handling** | zipfile | Распаковка и анализ архивов |
|
||||||
|
| **Async Runtime** | asyncio | Конкурентная обработка запросов |
|
||||||
|
|
||||||
|
## 📦 Установка и развертывание
|
||||||
|
|
||||||
|
### Системные требования
|
||||||
|
- Python 3.10 или выше
|
||||||
|
- pip package manager
|
||||||
|
- Telegram Bot Token (получить у [@BotFather](https://t.me/botfather))
|
||||||
|
|
||||||
|
### Процедура установки
|
||||||
|
|
||||||
```bash
|
```bash
|
||||||
pip install md2gost
|
# Клонирование репозитория
|
||||||
md2gost report.md # рядом появится report.docx
|
git clone https://github.com/EDeev/my_converterbot.git
|
||||||
md2gost report.md -o out.docx --no-heading-numbers
|
cd my_converterbot
|
||||||
|
|
||||||
|
# Установка зависимостей
|
||||||
|
pip install -r requirements.txt
|
||||||
|
|
||||||
|
# Конфигурация токена
|
||||||
|
# Отредактируйте bot.py, установите ваш BOT_TOKEN
|
||||||
|
# BOT_TOKEN = "your_telegram_bot_token_here"
|
||||||
|
|
||||||
|
# Запуск бота
|
||||||
|
python bot.py
|
||||||
```
|
```
|
||||||
|
|
||||||
Что делает с документом:
|
## 🚀 Использование
|
||||||
|
|
||||||
- поля: левое 30 мм, правое 15, верхнее и нижнее 20; Times New Roman 14 пт, интервал 1,5, абзацный отступ 1,25 см, выравнивание по ширине
|
### Базовые команды
|
||||||
- номера страниц внизу по центру, без номера на титульном листе
|
- `/start` — инициализация и приветственное сообщение
|
||||||
- нумерация разделов `1.`, `1.1.`, `1.1.1.`; «Введение», «Заключение», «Список литературы» и другие
|
- `/help` — детальная документация по функциям
|
||||||
структурные элементы — без номера, прописными, по центру
|
|
||||||
- разрыв страницы перед каждым разделом второго уровня
|
|
||||||
- маркированные списки с тире и вложенностью, нумерованные — `1)`, своя нумерация у каждого списка
|
|
||||||
- таблицы с подписью «Таблица N» слева сверху, блоки и вставки кода моноширинным шрифтом, цитаты,
|
|
||||||
сноски `[^1]`, жирный и курсив
|
|
||||||
|
|
||||||
Параметры командной строки: `--font`, `--size`, `--spacing`, `--no-heading-numbers`, `--no-page-numbers`,
|
### Рабочий процесс
|
||||||
`--number-title-page`. Из Python:
|
|
||||||
|
#### Markdown → DOCX конвертация
|
||||||
|
1. Отправьте `.md` файл боту
|
||||||
|
2. Система автоматически применит ГОСТ форматирование
|
||||||
|
3. Получите готовый `.docx` документ
|
||||||
|
|
||||||
|
**Пример входного Markdown:**
|
||||||
|
```markdown
|
||||||
|
# Введение
|
||||||
|
|
||||||
|
Основной текст с **жирным** и *курсивным* форматированием[^1].
|
||||||
|
|
||||||
|
## 1. Методология
|
||||||
|
|
||||||
|
- Пункт списка 1
|
||||||
|
- Пункт списка 2
|
||||||
|
|
||||||
|
[^1]: Текст сноски
|
||||||
|
```
|
||||||
|
|
||||||
|
#### ZIP → TXT анализ
|
||||||
|
1. Отправьте `.zip` архив с проектом
|
||||||
|
2. Бот извлечет и проанализирует структуру
|
||||||
|
3. Получите `project_structure.txt` с полным содержимым
|
||||||
|
|
||||||
|
## ⚙️ Архитектурные особенности
|
||||||
|
|
||||||
|
### Модульная структура
|
||||||
|
|
||||||
|
```
|
||||||
|
my_converterbot/
|
||||||
|
├── bot.py # Основной модуль Telegram бота
|
||||||
|
├── md_to_docx.py # Конвертер Markdown с ГОСТ движком
|
||||||
|
├── rep_to_txt.py # Анализатор проектных структур
|
||||||
|
├── requirements.txt # Спецификация зависимостей
|
||||||
|
└── README.md # Текущая документация
|
||||||
|
```
|
||||||
|
|
||||||
|
### DocumentSettings: Параметрическая конфигурация
|
||||||
|
|
||||||
|
Класс `DocumentSettings` обеспечивает гранулярное управление:
|
||||||
|
- Размеры шрифтов (14pt основной текст, 16pt заголовки первого уровня)
|
||||||
|
- Отступы документа (левый: 3.0 см для переплета)
|
||||||
|
- Режимы нумерации (decimal: 1.1.1 или simple: 1)
|
||||||
|
- Позиционирование номеров страниц
|
||||||
|
|
||||||
|
### Интеллектуальная обработка
|
||||||
|
|
||||||
|
**Алгоритм обработки списков:**
|
||||||
|
- Распознавание вложенности через отступы
|
||||||
|
- Автоматическая замена bullet points на длинное тире (ГОСТ)
|
||||||
|
- Сохранение иерархической структуры
|
||||||
|
|
||||||
|
**Система обработки сносок:**
|
||||||
|
- Inline маркеры `[^1]` → верхний индекс в тексте
|
||||||
|
- Автоматическая агрегация определений
|
||||||
|
- Размещение в конце документа с разделителем
|
||||||
|
|
||||||
|
## 🔒 Ограничения и constraints
|
||||||
|
|
||||||
|
- **Максимальный размер файла**: 20 МБ (Telegram API limitation)
|
||||||
|
- **Поддерживаемые форматы входных данных**: `.md`, `.zip`
|
||||||
|
- **Кодировки**: UTF-8, UTF-8-sig, CP1251, Latin1 (fallback цепочка)
|
||||||
|
|
||||||
|
## 📊 Производительность
|
||||||
|
|
||||||
|
- **Обработка Markdown**: ~0.5-2 сек для документов до 50 страниц
|
||||||
|
- **Анализ ZIP архивов**: ~1-5 сек для проектов до 1000 файлов
|
||||||
|
- **Конкурентная обработка**: до 10 одновременных запросов
|
||||||
|
|
||||||
|
## 🛠️ Расширение функциональности
|
||||||
|
|
||||||
|
### Кастомизация ГОСТ параметров
|
||||||
|
|
||||||
```python
|
```python
|
||||||
from md2gost import DocumentSettings, MarkdownToDocxConverter
|
from md_to_docx import MarkdownToDocxConverter, DocumentSettings
|
||||||
|
|
||||||
settings = DocumentSettings()
|
settings = DocumentSettings()
|
||||||
|
settings.font_name = "Times New Roman"
|
||||||
|
settings.font_size = 14
|
||||||
|
settings.line_spacing = 1.5
|
||||||
|
settings.margin_left = 3.0
|
||||||
settings.auto_numbering_headings = True
|
settings.auto_numbering_headings = True
|
||||||
MarkdownToDocxConverter(settings).convert("report.md", "report.docx")
|
settings.numbering_format = "decimal"
|
||||||
|
|
||||||
|
converter = MarkdownToDocxConverter(settings)
|
||||||
|
converter.convert("input.md", "output.docx")
|
||||||
```
|
```
|
||||||
|
|
||||||
Разбор Markdown свой и построчный: вложенные таблицы и списки внутри таблиц не поддерживаются.
|
## 📄 Лицензия
|
||||||
|
|
||||||
## Бот
|
Этот проект является некоммерческим и распространяется под лицензией MIT.
|
||||||
|
|
||||||
| Прислать | Получить |
|
## 👨💻 Автор
|
||||||
|---|---|
|
|
||||||
| `.md` | `.docx` по ГОСТ (тот же md2gost с нумерацией заголовков) |
|
|
||||||
| `.zip` с проектом | `.txt`: дерево папок и содержимое текстовых файлов с номерами строк — удобно отдать в LLM или приложить к отчёту |
|
|
||||||
|
|
||||||
Файлы — до 20 МБ. Архив проверяется до распаковки: не больше 5000 файлов и 200 МБ в распакованном виде.
|
**Деев Егор Викторович** - Backend Developer
|
||||||
Служебные папки (`.git`, `node_modules`, `__pycache__`, `build`…) и бинарные файлы пропускаются.
|
- GitHub: [@EDeev](https://github.com/EDeev)
|
||||||
Конвертация идёт в отдельном потоке, поэтому бот не замирает на больших файлах.
|
- Email: egor@deev.space
|
||||||
|
- Telegram: [@Egor_Deev](https://t.me/Egor_Deev)
|
||||||
```bash
|
|
||||||
git clone https://github.com/EDeev/my_converterbot.git && cd my_converterbot
|
|
||||||
cp .env.example .env # BOT_TOKEN от @BotFather
|
|
||||||
docker compose up -d
|
|
||||||
```
|
|
||||||
|
|
||||||
Готовый образ: `docker pull ghcr.io/edeev/my_converterbot` или `docker pull dcr.deev.su/edeev/my_converterbot`.
|
|
||||||
Без Docker: `pip install -r requirements.txt`, затем `BOT_TOKEN=… python bot.py`.
|
|
||||||
|
|
||||||
`rep_to_txt.py` работает и сам по себе: `python rep_to_txt.py путь/к/проекту`.
|
|
||||||
|
|
||||||
## Структура
|
|
||||||
|
|
||||||
```
|
|
||||||
md2gost/converter.py конвертер: настройки DocumentSettings и MarkdownToDocxConverter
|
|
||||||
md2gost/cli.py командная строка md2gost
|
|
||||||
bot.py Telegram-бот
|
|
||||||
rep_to_txt.py дерево проекта и содержимое файлов в один .txt
|
|
||||||
tests/ тесты конвертера и бота
|
|
||||||
```
|
|
||||||
|
|
||||||
## Разработка
|
|
||||||
|
|
||||||
```bash
|
|
||||||
pip install -r requirements-dev.txt
|
|
||||||
ruff check --select E9,F,B . && pytest
|
|
||||||
```
|
|
||||||
|
|
||||||
CI проверяет пакет на Python 3.9, 3.12 и 3.13 и собирает его. По тегу `v*` пакет публикуется на PyPI, а
|
|
||||||
Docker-образ бота — в GitHub Packages и `dcr.deev.su`.
|
|
||||||
|
|
||||||
## Лицензия
|
|
||||||
|
|
||||||
MIT — см. [LICENSE](LICENSE).
|
|
||||||
|
|
||||||
## Автор
|
|
||||||
|
|
||||||
**Деев Егор Викторович** — [GitHub](https://github.com/EDeev) · [Telegram](https://t.me/DeevEgor) · [egor@deev.space](mailto:egor@deev.space)
|
|
||||||
|
|
||||||
---
|
---
|
||||||
|
|
||||||
<div align="center">
|
<div align="center">
|
||||||
<sub>⭐ Если проект оказался полезным, поставьте звёздочку на GitHub!</sub>
|
<sub>⭐ Если проект оказался полезным, поставьте звездочку на GitHub!</sub>
|
||||||
<p><sub>Сделано с ❤️ — <a href="https://deev.space">deev.space</a></sub></p>
|
<p><sub>Создано с ❤️ от вашего дорогого - deev.space ©</sub></p>
|
||||||
</div>
|
</div>
|
||||||
|
|
|
||||||
56
bot.py
56
bot.py
|
|
@ -1,6 +1,7 @@
|
||||||
import asyncio
|
import asyncio
|
||||||
import logging
|
import logging
|
||||||
import os
|
import os
|
||||||
|
import shutil
|
||||||
import zipfile
|
import zipfile
|
||||||
from pathlib import Path
|
from pathlib import Path
|
||||||
from tempfile import TemporaryDirectory
|
from tempfile import TemporaryDirectory
|
||||||
|
|
@ -13,15 +14,11 @@ from aiogram.fsm.storage.memory import MemoryStorage
|
||||||
from aiogram.client.bot import DefaultBotProperties
|
from aiogram.client.bot import DefaultBotProperties
|
||||||
|
|
||||||
# Импорт наших конвертеров
|
# Импорт наших конвертеров
|
||||||
from md2gost import MarkdownToDocxConverter, DocumentSettings
|
from md_to_docx import MarkdownToDocxConverter, DocumentSettings
|
||||||
from rep_to_txt import generate_complete_project_structure
|
from rep_to_txt import generate_complete_project_structure
|
||||||
|
|
||||||
# Конфигурация
|
# Конфигурация
|
||||||
BOT_TOKEN = os.getenv("BOT_TOKEN", "XXXXXXXXXXXXXXXXXXXXXXXX") # @my_convbot
|
BOT_TOKEN = "**************************" # @my_convbot
|
||||||
|
|
||||||
MAX_FILE_SIZE = 20 * 1024 * 1024 # больше Telegram-боту не скачать
|
|
||||||
MAX_UNPACKED_SIZE = 200 * 1024 * 1024 # защита от zip-бомбы
|
|
||||||
MAX_FILES_IN_ARCHIVE = 5000
|
|
||||||
|
|
||||||
# Инициализация бота
|
# Инициализация бота
|
||||||
bot = Bot(token=BOT_TOKEN, default=DefaultBotProperties(parse_mode=ParseMode.HTML))
|
bot = Bot(token=BOT_TOKEN, default=DefaultBotProperties(parse_mode=ParseMode.HTML))
|
||||||
|
|
@ -63,18 +60,14 @@ async def help_handler(msg: Message) -> None:
|
||||||
async def handle_document(msg: Message) -> None:
|
async def handle_document(msg: Message) -> None:
|
||||||
"""Обработка загруженных документов"""
|
"""Обработка загруженных документов"""
|
||||||
document = msg.document
|
document = msg.document
|
||||||
# у документа может не быть имени; путь берём только из имени файла, без каталогов
|
file_name = document.file_name
|
||||||
file_name = Path(document.file_name or "file").name
|
file_size = document.file_size
|
||||||
file_size = document.file_size or 0
|
|
||||||
|
|
||||||
if file_size > MAX_FILE_SIZE:
|
if file_size > 20 * 1024 * 1024:
|
||||||
await msg.answer("❌ Файл слишком большой! Максимум 20 МБ")
|
await msg.answer("❌ Файл слишком большой! Максимум 20 МБ")
|
||||||
return
|
return
|
||||||
|
|
||||||
file_ext = Path(file_name).suffix.lower()
|
file_ext = Path(file_name).suffix.lower()
|
||||||
if file_ext not in (".md", ".zip"):
|
|
||||||
await msg.answer("❌ Неподдерживаемый формат файла! Пришлите .md или .zip")
|
|
||||||
return
|
|
||||||
|
|
||||||
status_msg = await msg.answer("⏳ Обрабатываю файл...")
|
status_msg = await msg.answer("⏳ Обрабатываю файл...")
|
||||||
|
|
||||||
|
|
@ -85,16 +78,20 @@ async def handle_document(msg: Message) -> None:
|
||||||
input_path = os.path.join(temp_dir, file_name)
|
input_path = os.path.join(temp_dir, file_name)
|
||||||
await bot.download_file(file_info.file_path, input_path)
|
await bot.download_file(file_info.file_path, input_path)
|
||||||
|
|
||||||
# конвертация — в отдельном потоке, чтобы бот не замирал для остальных
|
|
||||||
if file_ext == '.md':
|
if file_ext == '.md':
|
||||||
# Конвертация MD → DOCX
|
# Конвертация MD → DOCX
|
||||||
output_path = await asyncio.to_thread(convert_md_to_docx, input_path, temp_dir)
|
output_path = await convert_md_to_docx(input_path, temp_dir)
|
||||||
output_name = Path(file_name).stem + '.docx'
|
output_name = Path(file_name).stem + '.docx'
|
||||||
else:
|
|
||||||
|
elif file_ext in ['.zip']:
|
||||||
# Анализ архива → TXT
|
# Анализ архива → TXT
|
||||||
output_path = await asyncio.to_thread(analyze_archive, input_path, temp_dir)
|
output_path = await analyze_archive(input_path, temp_dir, file_ext)
|
||||||
output_name = Path(file_name).stem + '_structure.txt'
|
output_name = Path(file_name).stem + '_structure.txt'
|
||||||
|
|
||||||
|
else:
|
||||||
|
await status_msg.edit_text("❌ Неподдерживаемый формат файла!")
|
||||||
|
return
|
||||||
|
|
||||||
# Отправка результата
|
# Отправка результата
|
||||||
with open(output_path, 'rb') as output_file:
|
with open(output_path, 'rb') as output_file:
|
||||||
result_file = BufferedInputFile(
|
result_file = BufferedInputFile(
|
||||||
|
|
@ -105,20 +102,11 @@ async def handle_document(msg: Message) -> None:
|
||||||
|
|
||||||
await status_msg.edit_text("✅ Конвертация завершена!")
|
await status_msg.edit_text("✅ Конвертация завершена!")
|
||||||
|
|
||||||
except ArchiveTooLarge as e:
|
|
||||||
await status_msg.edit_text(f"❌ {e}")
|
|
||||||
except zipfile.BadZipFile:
|
|
||||||
await status_msg.edit_text("❌ Архив повреждён или это не .zip")
|
|
||||||
except Exception as e:
|
except Exception as e:
|
||||||
logger.exception("Ошибка обработки файла")
|
logger.error(f"Ошибка обработки файла: {e}")
|
||||||
await status_msg.edit_text(f"❌ Ошибка обработки: {str(e)}")
|
await status_msg.edit_text(f"❌ Ошибка обработки: {str(e)}")
|
||||||
|
|
||||||
|
async def convert_md_to_docx(md_path: str, temp_dir: str) -> str:
|
||||||
class ArchiveTooLarge(Exception):
|
|
||||||
pass
|
|
||||||
|
|
||||||
|
|
||||||
def convert_md_to_docx(md_path: str, temp_dir: str) -> str:
|
|
||||||
"""Конвертация Markdown в DOCX"""
|
"""Конвертация Markdown в DOCX"""
|
||||||
output_path = os.path.join(temp_dir, "output.docx")
|
output_path = os.path.join(temp_dir, "output.docx")
|
||||||
|
|
||||||
|
|
@ -135,23 +123,13 @@ def convert_md_to_docx(md_path: str, temp_dir: str) -> str:
|
||||||
|
|
||||||
return output_path
|
return output_path
|
||||||
|
|
||||||
def check_archive(zip_ref: zipfile.ZipFile) -> None:
|
async def analyze_archive(archive_path: str, temp_dir: str, file_ext: str) -> str:
|
||||||
"""Архив на 20 МБ может распаковаться в гигабайты и забить диск — проверяем до распаковки"""
|
|
||||||
infos = zip_ref.infolist()
|
|
||||||
if len(infos) > MAX_FILES_IN_ARCHIVE:
|
|
||||||
raise ArchiveTooLarge(f"В архиве больше {MAX_FILES_IN_ARCHIVE} файлов")
|
|
||||||
if sum(info.file_size for info in infos) > MAX_UNPACKED_SIZE:
|
|
||||||
raise ArchiveTooLarge(f"Распакованный архив больше {MAX_UNPACKED_SIZE // 1024 // 1024} МБ")
|
|
||||||
|
|
||||||
|
|
||||||
def analyze_archive(archive_path: str, temp_dir: str) -> str:
|
|
||||||
"""Анализ архива и создание структуры проекта"""
|
"""Анализ архива и создание структуры проекта"""
|
||||||
extract_dir = os.path.join(temp_dir, "extracted")
|
extract_dir = os.path.join(temp_dir, "extracted")
|
||||||
os.makedirs(extract_dir, exist_ok=True)
|
os.makedirs(extract_dir, exist_ok=True)
|
||||||
|
|
||||||
# Извлечение архива
|
# Извлечение архива
|
||||||
with zipfile.ZipFile(archive_path, 'r') as zip_ref:
|
with zipfile.ZipFile(archive_path, 'r') as zip_ref:
|
||||||
check_archive(zip_ref)
|
|
||||||
zip_ref.extractall(extract_dir)
|
zip_ref.extractall(extract_dir)
|
||||||
|
|
||||||
# Поиск основной папки проекта
|
# Поиск основной папки проекта
|
||||||
|
|
|
||||||
|
|
@ -1,6 +0,0 @@
|
||||||
services:
|
|
||||||
bot:
|
|
||||||
build: .
|
|
||||||
image: ghcr.io/edeev/my_converterbot:latest
|
|
||||||
env_file: .env
|
|
||||||
restart: unless-stopped
|
|
||||||
BIN
docs/demo.png
BIN
docs/demo.png

Binary file not shown.
|
Before Width: | Height: | Size: 98 KiB |
|
|
@ -1,6 +0,0 @@
|
||||||
"""md2gost — Markdown в DOCX по ГОСТ 7.32-2017"""
|
|
||||||
|
|
||||||
from .converter import DocumentSettings, MarkdownToDocxConverter
|
|
||||||
|
|
||||||
__version__ = "1.0.0"
|
|
||||||
__all__ = ["DocumentSettings", "MarkdownToDocxConverter", "__version__"]
|
|
||||||
|
|
@ -1,5 +0,0 @@
|
||||||
import sys
|
|
||||||
|
|
||||||
from .cli import main
|
|
||||||
|
|
||||||
sys.exit(main())
|
|
||||||
|
|
@ -1,47 +0,0 @@
|
||||||
import argparse
|
|
||||||
import sys
|
|
||||||
from pathlib import Path
|
|
||||||
|
|
||||||
from . import __version__
|
|
||||||
from .converter import DocumentSettings, MarkdownToDocxConverter
|
|
||||||
|
|
||||||
|
|
||||||
def build_parser():
|
|
||||||
parser = argparse.ArgumentParser(
|
|
||||||
prog="md2gost",
|
|
||||||
description="Конвертирует Markdown в DOCX, оформленный по ГОСТ 7.32-2017: поля, шрифт, интервалы, "
|
|
||||||
"нумерация страниц и заголовков, таблицы, списки, сноски, список литературы.",
|
|
||||||
)
|
|
||||||
parser.add_argument("input", type=Path, help="файл .md")
|
|
||||||
parser.add_argument("-o", "--output", type=Path, help="куда сохранить .docx (по умолчанию — рядом с .md)")
|
|
||||||
parser.add_argument("--font", default="Times New Roman", help="шрифт (по умолчанию Times New Roman)")
|
|
||||||
parser.add_argument("--size", type=int, default=14, help="размер основного текста, пт (по умолчанию 14)")
|
|
||||||
parser.add_argument("--spacing", type=float, default=1.5, help="межстрочный интервал (по умолчанию 1.5)")
|
|
||||||
parser.add_argument("--no-heading-numbers", action="store_true", help="не нумеровать заголовки")
|
|
||||||
parser.add_argument("--no-page-numbers", action="store_true", help="не нумеровать страницы")
|
|
||||||
parser.add_argument("--number-title-page", action="store_true", help="ставить номер и на первой странице")
|
|
||||||
parser.add_argument("--version", action="version", version=f"%(prog)s {__version__}")
|
|
||||||
return parser
|
|
||||||
|
|
||||||
|
|
||||||
def main(argv=None):
|
|
||||||
args = build_parser().parse_args(argv)
|
|
||||||
if not args.input.is_file():
|
|
||||||
print(f"md2gost: файл не найден: {args.input}", file=sys.stderr)
|
|
||||||
return 1
|
|
||||||
|
|
||||||
settings = DocumentSettings()
|
|
||||||
settings.font_name = args.font
|
|
||||||
settings.font_size = args.size
|
|
||||||
settings.line_spacing = args.spacing
|
|
||||||
settings.auto_numbering_headings = not args.no_heading_numbers
|
|
||||||
settings.page_numbering = not args.no_page_numbers
|
|
||||||
settings.exclude_title_page_numbering = not args.number_title_page
|
|
||||||
|
|
||||||
output = MarkdownToDocxConverter(settings).convert(str(args.input), str(args.output) if args.output else None)
|
|
||||||
print(output)
|
|
||||||
return 0
|
|
||||||
|
|
||||||
|
|
||||||
if __name__ == "__main__":
|
|
||||||
sys.exit(main())
|
|
||||||
|
|
@ -1,52 +1,17 @@
|
||||||
|
#!/usr/bin/env python3
|
||||||
|
# -*- coding: utf-8 -*-
|
||||||
|
|
||||||
import re
|
import re
|
||||||
|
import sys
|
||||||
from pathlib import Path
|
from pathlib import Path
|
||||||
|
|
||||||
from docx import Document
|
from docx import Document
|
||||||
from docx.enum.style import WD_STYLE_TYPE
|
from docx.shared import Inches, Pt, RGBColor, Cm
|
||||||
from docx.enum.text import WD_ALIGN_PARAGRAPH, WD_LINE_SPACING
|
from docx.enum.text import WD_ALIGN_PARAGRAPH, WD_LINE_SPACING
|
||||||
|
from docx.enum.style import WD_STYLE_TYPE
|
||||||
|
from docx.enum.section import WD_SECTION
|
||||||
from docx.oxml.shared import OxmlElement, qn
|
from docx.oxml.shared import OxmlElement, qn
|
||||||
from docx.shared import Cm, Inches, Pt, RGBColor
|
from docx.oxml.ns import nsdecls
|
||||||
|
from docx.oxml import parse_xml
|
||||||
# Структурные элементы по ГОСТ 7.32-2017 — заголовки без номера
|
|
||||||
STRUCTURAL_HEADINGS = re.compile(
|
|
||||||
r"^(реферат|содержание|оглавление|введение|заключение|список\s+(использованных\s+)?(литературы|источников)"
|
|
||||||
r"|библиография|bibliography|references|приложени[ея].*|термины\s+и\s+определения"
|
|
||||||
r"|перечень\s+сокращений.*|определения|обозначения\s+и\s+сокращения)$",
|
|
||||||
re.IGNORECASE,
|
|
||||||
)
|
|
||||||
BIBLIOGRAPHY_HEADING = re.compile(
|
|
||||||
r"^(список\s+(использованных\s+)?(литературы|источников)|библиография|bibliography|references)$",
|
|
||||||
re.IGNORECASE,
|
|
||||||
)
|
|
||||||
|
|
||||||
|
|
||||||
def set_style_font(style, font_name):
|
|
||||||
"""Шрифт стиля для всех письменностей. Встроенные стили Word (заголовки) задают шрифт темы
|
|
||||||
(asciiTheme и т. п.), который перекрывает font.name — без очистки заголовки выходят в Calibri"""
|
|
||||||
style.font.name = font_name
|
|
||||||
rpr = style.element.get_or_add_rPr()
|
|
||||||
rfonts = rpr.find(qn("w:rFonts"))
|
|
||||||
if rfonts is None:
|
|
||||||
rfonts = OxmlElement("w:rFonts")
|
|
||||||
rpr.append(rfonts)
|
|
||||||
for attr in ("w:asciiTheme", "w:hAnsiTheme", "w:eastAsiaTheme", "w:cstheme"):
|
|
||||||
rfonts.attrib.pop(qn(attr), None)
|
|
||||||
for attr in ("w:ascii", "w:hAnsi", "w:eastAsia", "w:cs"):
|
|
||||||
rfonts.set(qn(attr), font_name)
|
|
||||||
|
|
||||||
|
|
||||||
def add_page_field(paragraph):
|
|
||||||
"""Поле PAGE — номер страницы, который Word подставляет сам"""
|
|
||||||
run = paragraph.add_run()
|
|
||||||
begin, instr, end = OxmlElement("w:fldChar"), OxmlElement("w:instrText"), OxmlElement("w:fldChar")
|
|
||||||
begin.set(qn("w:fldCharType"), "begin")
|
|
||||||
instr.set(qn("xml:space"), "preserve")
|
|
||||||
instr.text = "PAGE"
|
|
||||||
end.set(qn("w:fldCharType"), "end")
|
|
||||||
run._r.append(begin)
|
|
||||||
run._r.append(instr)
|
|
||||||
run._r.append(end)
|
|
||||||
return run
|
|
||||||
|
|
||||||
|
|
||||||
class DocumentSettings:
|
class DocumentSettings:
|
||||||
|
|
@ -131,23 +96,21 @@ class MarkdownToDocxConverter:
|
||||||
|
|
||||||
section = self.doc.sections[0]
|
section = self.doc.sections[0]
|
||||||
|
|
||||||
# Создание колонтитула для нумерации (раньше колонтитул создавался, но поле номера
|
# Создание колонтитула для нумерации
|
||||||
# страницы в него не добавлялось — номеров в документе не было)
|
if self.settings.page_number_position == "bottom_center":
|
||||||
if self.settings.page_number_position == "top_right":
|
footer = section.footer
|
||||||
para = section.header.paragraphs[0]
|
footer_para = footer.paragraphs[0]
|
||||||
para.alignment = WD_ALIGN_PARAGRAPH.RIGHT
|
footer_para.alignment = WD_ALIGN_PARAGRAPH.CENTER
|
||||||
else:
|
|
||||||
para = section.footer.paragraphs[0]
|
|
||||||
para.alignment = (WD_ALIGN_PARAGRAPH.RIGHT if self.settings.page_number_position == "bottom_right"
|
|
||||||
else WD_ALIGN_PARAGRAPH.CENTER)
|
|
||||||
para.paragraph_format.first_line_indent = Cm(0)
|
|
||||||
run = add_page_field(para)
|
|
||||||
run.font.name = self.settings.font_name
|
|
||||||
run.font.size = Pt(self.settings.font_size)
|
|
||||||
|
|
||||||
# титульный лист без номера: у первой страницы свой, пустой колонтитул
|
elif self.settings.page_number_position == "top_right":
|
||||||
if self.settings.exclude_title_page_numbering:
|
header = section.header
|
||||||
section.different_first_page_header_footer = True
|
header_para = header.paragraphs[0]
|
||||||
|
header_para.alignment = WD_ALIGN_PARAGRAPH.RIGHT
|
||||||
|
|
||||||
|
elif self.settings.page_number_position == "bottom_right":
|
||||||
|
footer = section.footer
|
||||||
|
footer_para = footer.paragraphs[0]
|
||||||
|
footer_para.alignment = WD_ALIGN_PARAGRAPH.RIGHT
|
||||||
|
|
||||||
def setup_styles(self):
|
def setup_styles(self):
|
||||||
"""Настройка стилей документа в соответствии с ГОСТ"""
|
"""Настройка стилей документа в соответствии с ГОСТ"""
|
||||||
|
|
@ -156,7 +119,7 @@ class MarkdownToDocxConverter:
|
||||||
# Настройка базового стиля
|
# Настройка базового стиля
|
||||||
normal_style = styles['Normal']
|
normal_style = styles['Normal']
|
||||||
normal_font = normal_style.font
|
normal_font = normal_style.font
|
||||||
set_style_font(normal_style, self.settings.font_name)
|
normal_font.name = self.settings.font_name
|
||||||
normal_font.size = Pt(self.settings.font_size)
|
normal_font.size = Pt(self.settings.font_size)
|
||||||
normal_font.color.rgb = RGBColor(*self.settings.text_color)
|
normal_font.color.rgb = RGBColor(*self.settings.text_color)
|
||||||
|
|
||||||
|
|
@ -188,10 +151,9 @@ class MarkdownToDocxConverter:
|
||||||
heading_style = styles.add_style(heading_style_name, WD_STYLE_TYPE.PARAGRAPH)
|
heading_style = styles.add_style(heading_style_name, WD_STYLE_TYPE.PARAGRAPH)
|
||||||
|
|
||||||
heading_font = heading_style.font
|
heading_font = heading_style.font
|
||||||
set_style_font(heading_style, self.settings.font_name)
|
heading_font.name = self.settings.font_name
|
||||||
heading_font.size = Pt(heading_sizes[i-1]) # используем соответствующий размер
|
heading_font.size = Pt(heading_sizes[i-1]) # используем соответствующий размер
|
||||||
heading_font.bold = True
|
heading_font.bold = True
|
||||||
heading_font.italic = False
|
|
||||||
heading_font.color.rgb = RGBColor(*self.settings.text_color)
|
heading_font.color.rgb = RGBColor(*self.settings.text_color)
|
||||||
|
|
||||||
heading_paragraph = heading_style.paragraph_format
|
heading_paragraph = heading_style.paragraph_format
|
||||||
|
|
@ -219,24 +181,24 @@ class MarkdownToDocxConverter:
|
||||||
footnote_paragraph.space_before = Pt(3)
|
footnote_paragraph.space_before = Pt(3)
|
||||||
footnote_paragraph.space_after = Pt(3)
|
footnote_paragraph.space_after = Pt(3)
|
||||||
footnote_paragraph.first_line_indent = Cm(0.5)
|
footnote_paragraph.first_line_indent = Cm(0.5)
|
||||||
except ValueError: # стиль уже есть
|
except:
|
||||||
pass
|
pass
|
||||||
|
|
||||||
# Стиль для кода (без изменений)
|
# Стиль для кода (без изменений)
|
||||||
try:
|
try:
|
||||||
code_style = styles.add_style('Code', WD_STYLE_TYPE.CHARACTER)
|
code_style = styles.add_style('Code', WD_STYLE_TYPE.CHARACTER)
|
||||||
code_font = code_style.font
|
code_font = code_style.font
|
||||||
set_style_font(code_style, 'Courier New')
|
code_font.name = 'Courier New'
|
||||||
code_font.size = Pt(self.settings.font_size)
|
code_font.size = Pt(self.settings.font_size)
|
||||||
code_font.color.rgb = RGBColor(*self.settings.text_color)
|
code_font.color.rgb = RGBColor(*self.settings.text_color)
|
||||||
except ValueError: # стиль уже есть
|
except:
|
||||||
pass
|
pass
|
||||||
|
|
||||||
# Стиль для блоков кода
|
# Стиль для блоков кода
|
||||||
try:
|
try:
|
||||||
code_block_style = styles.add_style('Code Block', WD_STYLE_TYPE.PARAGRAPH)
|
code_block_style = styles.add_style('Code Block', WD_STYLE_TYPE.PARAGRAPH)
|
||||||
code_block_font = code_block_style.font
|
code_block_font = code_block_style.font
|
||||||
set_style_font(code_block_style, 'Courier New')
|
code_block_font.name = 'Courier New'
|
||||||
code_block_font.size = Pt(self.settings.font_size)
|
code_block_font.size = Pt(self.settings.font_size)
|
||||||
code_block_font.color.rgb = RGBColor(*self.settings.text_color)
|
code_block_font.color.rgb = RGBColor(*self.settings.text_color)
|
||||||
|
|
||||||
|
|
@ -245,25 +207,23 @@ class MarkdownToDocxConverter:
|
||||||
code_block_paragraph.first_line_indent = Cm(0) # без отступа первой строки для кода
|
code_block_paragraph.first_line_indent = Cm(0) # без отступа первой строки для кода
|
||||||
code_block_paragraph.space_before = Pt(6)
|
code_block_paragraph.space_before = Pt(6)
|
||||||
code_block_paragraph.space_after = Pt(6)
|
code_block_paragraph.space_after = Pt(6)
|
||||||
except ValueError: # стиль уже есть
|
except:
|
||||||
pass
|
pass
|
||||||
|
|
||||||
# Стиль для подписей к таблицам и рисункам
|
# Стиль для подписей к таблицам и рисункам
|
||||||
# «Caption» уже есть во встроенном шаблоне (синий, 9 пт) — настраиваем его, а не создаём
|
try:
|
||||||
caption_style = (styles['Caption'] if 'Caption' in [s.name for s in styles]
|
caption_style = styles.add_style('Caption', WD_STYLE_TYPE.PARAGRAPH)
|
||||||
else styles.add_style('Caption', WD_STYLE_TYPE.PARAGRAPH))
|
|
||||||
caption_font = caption_style.font
|
caption_font = caption_style.font
|
||||||
set_style_font(caption_style, self.settings.font_name)
|
caption_font.name = self.settings.font_name
|
||||||
caption_font.size = Pt(self.settings.font_size - 2) # меньше основного текста
|
caption_font.size = Pt(self.settings.font_size - 2) # меньше основного текста
|
||||||
caption_font.bold = False
|
|
||||||
caption_font.italic = False
|
|
||||||
caption_font.color.rgb = RGBColor(*self.settings.text_color)
|
caption_font.color.rgb = RGBColor(*self.settings.text_color)
|
||||||
|
|
||||||
caption_paragraph = caption_style.paragraph_format
|
caption_paragraph = caption_style.paragraph_format
|
||||||
caption_paragraph.alignment = WD_ALIGN_PARAGRAPH.CENTER
|
caption_paragraph.alignment = WD_ALIGN_PARAGRAPH.CENTER
|
||||||
caption_paragraph.first_line_indent = Cm(0)
|
|
||||||
caption_paragraph.space_before = Pt(6)
|
caption_paragraph.space_before = Pt(6)
|
||||||
caption_paragraph.space_after = Pt(6)
|
caption_paragraph.space_after = Pt(6)
|
||||||
|
except:
|
||||||
|
pass
|
||||||
|
|
||||||
def generate_heading_number(self, level: int) -> str:
|
def generate_heading_number(self, level: int) -> str:
|
||||||
"""Генерация номера заголовка согласно настройкам автонумерации"""
|
"""Генерация номера заголовка согласно настройкам автонумерации"""
|
||||||
|
|
@ -290,11 +250,11 @@ class MarkdownToDocxConverter:
|
||||||
def parse_markdown_file(self, file_path: str):
|
def parse_markdown_file(self, file_path: str):
|
||||||
"""Чтение и парсинг Markdown файла"""
|
"""Чтение и парсинг Markdown файла"""
|
||||||
try:
|
try:
|
||||||
with open(file_path, 'r', encoding='utf-8-sig') as file:
|
with open(file_path, 'r', encoding='utf-8') as file:
|
||||||
content = file.read()
|
content = file.read()
|
||||||
return content
|
return content
|
||||||
except Exception as e:
|
except Exception as e:
|
||||||
raise Exception(f"Ошибка чтения файла: {e}") from e
|
raise Exception(f"Ошибка чтения файла: {e}")
|
||||||
|
|
||||||
def add_text_run_with_color(self, paragraph, text, bold=False, italic=False, code_style=False):
|
def add_text_run_with_color(self, paragraph, text, bold=False, italic=False, code_style=False):
|
||||||
"""Добавление текста с настройкой цвета"""
|
"""Добавление текста с настройкой цвета"""
|
||||||
|
|
@ -345,74 +305,68 @@ class MarkdownToDocxConverter:
|
||||||
# Обычный текст
|
# Обычный текст
|
||||||
self.add_text_run_with_color(paragraph, part)
|
self.add_text_run_with_color(paragraph, part)
|
||||||
|
|
||||||
LIST_ITEM = re.compile(r'^(\s*)([-*+]|\d+[.)])\s+(.*)$')
|
|
||||||
|
|
||||||
def process_list(self, lines: list, start_idx: int):
|
def process_list(self, lines: list, start_idx: int):
|
||||||
"""Обработка списков с правильным форматированием по ГОСТ.
|
"""Обработка списков с правильным форматированием по ГОСТ"""
|
||||||
Маркер — тире, нумерация своя для каждого списка и уровня (раньше стиль List Bullet давал
|
|
||||||
второй маркер, вложенность терялась, а List Number продолжал счёт из предыдущего списка)"""
|
|
||||||
i = start_idx
|
i = start_idx
|
||||||
counters = {}
|
list_items = []
|
||||||
|
|
||||||
while i < len(lines):
|
while i < len(lines):
|
||||||
match = self.LIST_ITEM.match(lines[i].expandtabs(4))
|
line = lines[i].strip()
|
||||||
if not match:
|
|
||||||
if lines[i].strip() == '' and i + 1 < len(lines) and self.LIST_ITEM.match(lines[i + 1].expandtabs(4)):
|
if re.match(r'^[-*+]\s', line):
|
||||||
|
item_text = re.sub(r'^[-*+]\s', '', line)
|
||||||
|
list_items.append(('bullet', item_text, 0))
|
||||||
|
elif re.match(r'^\d+\.\s', line):
|
||||||
|
item_text = re.sub(r'^\d+\.\s', '', line)
|
||||||
|
list_items.append(('number', item_text, 0))
|
||||||
|
elif re.match(r'^ [-*+]\s', line):
|
||||||
|
item_text = re.sub(r'^ [-*+]\s', '', line)
|
||||||
|
list_items.append(('bullet', item_text, 1))
|
||||||
|
elif re.match(r'^ \d+\.\s', line):
|
||||||
|
item_text = re.sub(r'^ \d+\.\s', '', line)
|
||||||
|
list_items.append(('number', item_text, 1))
|
||||||
|
elif line == '':
|
||||||
i += 1
|
i += 1
|
||||||
continue
|
continue
|
||||||
break
|
|
||||||
|
|
||||||
indent, marker, text = match.groups()
|
|
||||||
level = min(len(indent) // 2, 3)
|
|
||||||
for deeper in [lvl for lvl in counters if lvl > level]:
|
|
||||||
del counters[deeper]
|
|
||||||
|
|
||||||
if marker[0].isdigit():
|
|
||||||
counters[level] = counters.get(level, 0) + 1
|
|
||||||
prefix = f"{counters[level]}) "
|
|
||||||
else:
|
else:
|
||||||
counters.pop(level, None)
|
break
|
||||||
prefix = "– " # тире вместо точек (ГОСТ)
|
|
||||||
|
|
||||||
paragraph = self.doc.add_paragraph()
|
|
||||||
paragraph.paragraph_format.left_indent = Cm(level * 0.75)
|
|
||||||
paragraph.paragraph_format.first_line_indent = Cm(self.settings.paragraph_indent)
|
|
||||||
self.add_text_run_with_color(paragraph, prefix)
|
|
||||||
self.process_text_formatting(text, paragraph)
|
|
||||||
i += 1
|
i += 1
|
||||||
|
|
||||||
|
# Добавление элементов списка с настройками ГОСТ
|
||||||
|
for list_type, text, level in list_items:
|
||||||
|
paragraph = self.doc.add_paragraph()
|
||||||
|
paragraph.paragraph_format.left_indent = Cm(level * 0.75) # увеличенный отступ для вложенности
|
||||||
|
paragraph.paragraph_format.first_line_indent = Cm(self.settings.paragraph_indent)
|
||||||
|
|
||||||
|
if list_type == 'bullet':
|
||||||
|
paragraph.style = 'List Bullet'
|
||||||
|
# Используем тире вместо точек (согласно ГОСТ)
|
||||||
|
bullet_run = paragraph.runs[0] if paragraph.runs else paragraph.add_run()
|
||||||
|
bullet_run.text = "– " # длинное тире
|
||||||
|
else:
|
||||||
|
paragraph.style = 'List Number'
|
||||||
|
|
||||||
|
self.process_text_formatting(text, paragraph)
|
||||||
|
|
||||||
return i - 1
|
return i - 1
|
||||||
|
|
||||||
TABLE_SEPARATOR = re.compile(r'^\|?\s*:?-+:?\s*(\|\s*:?-+:?\s*)*\|?$')
|
|
||||||
|
|
||||||
@staticmethod
|
|
||||||
def split_row(line: str) -> list:
|
|
||||||
"""Ячейки строки таблицы; внешние «|» необязательны"""
|
|
||||||
line = line.strip()
|
|
||||||
if line.startswith('|'):
|
|
||||||
line = line[1:]
|
|
||||||
if line.endswith('|'):
|
|
||||||
line = line[:-1]
|
|
||||||
return [cell.strip() for cell in line.split('|')]
|
|
||||||
|
|
||||||
def process_table(self, lines: list, start_idx: int):
|
def process_table(self, lines: list, start_idx: int):
|
||||||
"""Обработка таблиц с подписями согласно ГОСТ"""
|
"""Обработка таблиц с подписями согласно ГОСТ"""
|
||||||
i = start_idx
|
i = start_idx
|
||||||
table_lines = []
|
table_lines = []
|
||||||
|
|
||||||
# таблица заканчивается на пустой строке — иначе две таблицы подряд сливались в одну
|
|
||||||
while i < len(lines):
|
while i < len(lines):
|
||||||
line = lines[i].strip()
|
line = lines[i].strip()
|
||||||
if '|' in line:
|
if '|' in line:
|
||||||
table_lines.append(line)
|
table_lines.append(line)
|
||||||
|
elif line == '':
|
||||||
|
i += 1
|
||||||
|
continue
|
||||||
else:
|
else:
|
||||||
break
|
break
|
||||||
i += 1
|
i += 1
|
||||||
|
|
||||||
if len(table_lines) < 2 or not self.TABLE_SEPARATOR.match(table_lines[1]):
|
if len(table_lines) < 2:
|
||||||
# не таблица, а строка с «|» — обычный абзац
|
|
||||||
paragraph = self.doc.add_paragraph()
|
|
||||||
self.process_text_formatting(lines[start_idx].strip(), paragraph)
|
|
||||||
return start_idx
|
return start_idx
|
||||||
|
|
||||||
# Добавляем подпись к таблице (если настроено)
|
# Добавляем подпись к таблице (если настроено)
|
||||||
|
|
@ -420,11 +374,10 @@ class MarkdownToDocxConverter:
|
||||||
self.table_counter += 1
|
self.table_counter += 1
|
||||||
caption_para = self.doc.add_paragraph()
|
caption_para = self.doc.add_paragraph()
|
||||||
caption_para.style = 'Caption'
|
caption_para.style = 'Caption'
|
||||||
caption_para.alignment = WD_ALIGN_PARAGRAPH.LEFT
|
|
||||||
caption_para.add_run(f"Таблица {self.table_counter}")
|
caption_para.add_run(f"Таблица {self.table_counter}")
|
||||||
|
|
||||||
# Парсинг и создание таблицы
|
# Парсинг и создание таблицы
|
||||||
headers = self.split_row(table_lines[0])
|
headers = [cell.strip() for cell in table_lines[0].split('|')[1:-1]]
|
||||||
data_lines = table_lines[2:] if len(table_lines) > 2 else []
|
data_lines = table_lines[2:] if len(table_lines) > 2 else []
|
||||||
|
|
||||||
table = self.doc.add_table(rows=1, cols=len(headers))
|
table = self.doc.add_table(rows=1, cols=len(headers))
|
||||||
|
|
@ -442,7 +395,7 @@ class MarkdownToDocxConverter:
|
||||||
|
|
||||||
# Заполнение данных
|
# Заполнение данных
|
||||||
for line in data_lines:
|
for line in data_lines:
|
||||||
row_data = self.split_row(line)
|
row_data = [cell.strip() for cell in line.split('|')[1:-1]]
|
||||||
row = table.add_row()
|
row = table.add_row()
|
||||||
for idx, cell_data in enumerate(row_data):
|
for idx, cell_data in enumerate(row_data):
|
||||||
if idx < len(row.cells):
|
if idx < len(row.cells):
|
||||||
|
|
@ -451,23 +404,11 @@ class MarkdownToDocxConverter:
|
||||||
for paragraph in row.cells[idx].paragraphs:
|
for paragraph in row.cells[idx].paragraphs:
|
||||||
paragraph.alignment = WD_ALIGN_PARAGRAPH.CENTER
|
paragraph.alignment = WD_ALIGN_PARAGRAPH.CENTER
|
||||||
|
|
||||||
# в ячейках — без абзацного отступа и с одинарным интервалом, иначе текст смещён,
|
|
||||||
# а строки получаются высокими
|
|
||||||
for row in table.rows:
|
|
||||||
for cell in row.cells:
|
|
||||||
for paragraph in cell.paragraphs:
|
|
||||||
fmt = paragraph.paragraph_format
|
|
||||||
fmt.first_line_indent = Cm(0)
|
|
||||||
fmt.space_before = Pt(0)
|
|
||||||
fmt.space_after = Pt(0)
|
|
||||||
fmt.line_spacing = 1.0
|
|
||||||
|
|
||||||
# Подпись снизу (если настроено)
|
# Подпись снизу (если настроено)
|
||||||
if self.settings.table_caption_position == "below":
|
if self.settings.table_caption_position == "below":
|
||||||
self.table_counter += 1
|
self.table_counter += 1
|
||||||
caption_para = self.doc.add_paragraph()
|
caption_para = self.doc.add_paragraph()
|
||||||
caption_para.style = 'Caption'
|
caption_para.style = 'Caption'
|
||||||
caption_para.alignment = WD_ALIGN_PARAGRAPH.LEFT
|
|
||||||
caption_para.add_run(f"Таблица {self.table_counter}")
|
caption_para.add_run(f"Таблица {self.table_counter}")
|
||||||
|
|
||||||
return i - 1
|
return i - 1
|
||||||
|
|
@ -510,8 +451,8 @@ class MarkdownToDocxConverter:
|
||||||
# Поиск элементов библиографии
|
# Поиск элементов библиографии
|
||||||
while i < len(lines):
|
while i < len(lines):
|
||||||
line = lines[i].strip()
|
line = lines[i].strip()
|
||||||
if re.match(r'^(\d+[.)]|[-*+])\s', line):
|
if re.match(r'^\d+\.\s', line):
|
||||||
bib_text = re.sub(r'^(\d+[.)]|[-*+])\s', '', line)
|
bib_text = re.sub(r'^\d+\.\s', '', line)
|
||||||
bib_items.append(bib_text)
|
bib_items.append(bib_text)
|
||||||
elif line == '':
|
elif line == '':
|
||||||
i += 1
|
i += 1
|
||||||
|
|
@ -521,7 +462,12 @@ class MarkdownToDocxConverter:
|
||||||
i += 1
|
i += 1
|
||||||
|
|
||||||
if bib_items:
|
if bib_items:
|
||||||
# Элементы библиографии (заголовок уже добавлен в convert)
|
# Заголовок списка литературы
|
||||||
|
bib_heading = self.doc.add_paragraph()
|
||||||
|
bib_heading.style = 'Heading 1'
|
||||||
|
bib_heading.add_run("СПИСОК ЛИТЕРАТУРЫ")
|
||||||
|
|
||||||
|
# Элементы библиографии
|
||||||
for idx, item in enumerate(bib_items, 1):
|
for idx, item in enumerate(bib_items, 1):
|
||||||
bib_para = self.doc.add_paragraph()
|
bib_para = self.doc.add_paragraph()
|
||||||
bib_para.paragraph_format.first_line_indent = Cm(0)
|
bib_para.paragraph_format.first_line_indent = Cm(0)
|
||||||
|
|
@ -565,8 +511,7 @@ class MarkdownToDocxConverter:
|
||||||
match = re.match(r'^(#{1,6})\s+(.+)', stripped_line)
|
match = re.match(r'^(#{1,6})\s+(.+)', stripped_line)
|
||||||
if match:
|
if match:
|
||||||
level = len(match.group(1))
|
level = len(match.group(1))
|
||||||
title = match.group(2).strip()
|
title = match.group(2)
|
||||||
structural = bool(STRUCTURAL_HEADINGS.match(title.rstrip(':')))
|
|
||||||
|
|
||||||
# Разрыв страницы перед заголовком 2 уровня
|
# Разрыв страницы перед заголовком 2 уровня
|
||||||
if level == 2:
|
if level == 2:
|
||||||
|
|
@ -575,31 +520,28 @@ class MarkdownToDocxConverter:
|
||||||
heading = self.doc.add_paragraph()
|
heading = self.doc.add_paragraph()
|
||||||
heading.style = f'Heading {level}'
|
heading.style = f'Heading {level}'
|
||||||
|
|
||||||
if structural:
|
|
||||||
# структурные элементы (введение, заключение, список литературы...) по ГОСТ
|
|
||||||
# не нумеруются, пишутся прописными и по центру
|
|
||||||
heading.alignment = WD_ALIGN_PARAGRAPH.CENTER
|
|
||||||
heading.paragraph_format.first_line_indent = Cm(0)
|
|
||||||
self.process_text_formatting(title.upper(), heading)
|
|
||||||
if BIBLIOGRAPHY_HEADING.match(title.rstrip(':')):
|
|
||||||
i = self.process_bibliography(lines, i + 1)
|
|
||||||
else:
|
|
||||||
# Добавляем автонумерацию
|
# Добавляем автонумерацию
|
||||||
heading_number = self.generate_heading_number(level)
|
heading_number = self.generate_heading_number(level)
|
||||||
self.process_text_formatting(heading_number + title, heading)
|
full_title = heading_number + title
|
||||||
|
|
||||||
|
self.process_text_formatting(full_title, heading)
|
||||||
|
|
||||||
# Блоки кода
|
# Блоки кода
|
||||||
elif stripped_line.startswith('```'):
|
elif stripped_line.startswith('```'):
|
||||||
i = self.process_code_block(lines, i)
|
i = self.process_code_block(lines, i)
|
||||||
|
|
||||||
# Списки
|
|
||||||
elif self.LIST_ITEM.match(line.expandtabs(4)):
|
|
||||||
i = self.process_list(lines, i)
|
|
||||||
|
|
||||||
# Таблицы
|
# Таблицы
|
||||||
elif '|' in stripped_line:
|
elif '|' in stripped_line:
|
||||||
i = self.process_table(lines, i)
|
i = self.process_table(lines, i)
|
||||||
|
|
||||||
|
# Списки
|
||||||
|
elif re.match(r'^[-*+]\s', stripped_line) or re.match(r'^\d+\.\s', stripped_line):
|
||||||
|
i = self.process_list(lines, i)
|
||||||
|
|
||||||
|
# Список литературы (если заголовок содержит "литература" или "bibliography")
|
||||||
|
elif re.match(r'^#+\s*(список\s+литературы|bibliography|references)', stripped_line, re.IGNORECASE):
|
||||||
|
i = self.process_bibliography(lines, i + 1)
|
||||||
|
|
||||||
# Цитаты
|
# Цитаты
|
||||||
elif stripped_line.startswith('>'):
|
elif stripped_line.startswith('>'):
|
||||||
quote_text = re.sub(r'^>\s?', '', stripped_line)
|
quote_text = re.sub(r'^>\s?', '', stripped_line)
|
||||||
|
|
@ -634,3 +576,47 @@ class MarkdownToDocxConverter:
|
||||||
|
|
||||||
self.doc.save(output_path)
|
self.doc.save(output_path)
|
||||||
return output_path
|
return output_path
|
||||||
|
|
||||||
|
|
||||||
|
def main():
|
||||||
|
"""Основная функция для запуска из командной строки"""
|
||||||
|
if len(sys.argv) < 2:
|
||||||
|
print("Использование: python md_converter.py <путь_к_md_файлу> [путь_к_выходному_файлу]")
|
||||||
|
return
|
||||||
|
|
||||||
|
md_file = sys.argv[1]
|
||||||
|
output_file = sys.argv[2] if len(sys.argv) > 2 else None
|
||||||
|
|
||||||
|
# ГОСТ-совместимые настройки по умолчанию
|
||||||
|
settings = DocumentSettings()
|
||||||
|
|
||||||
|
converter = MarkdownToDocxConverter(settings)
|
||||||
|
|
||||||
|
try:
|
||||||
|
output_path = converter.convert(md_file, output_file)
|
||||||
|
print(f"Файл успешно конвертирован: {output_path}")
|
||||||
|
except Exception as e:
|
||||||
|
print(f"Ошибка конвертации: {e}")
|
||||||
|
|
||||||
|
|
||||||
|
if __name__ == "__main__":
|
||||||
|
main()
|
||||||
|
|
||||||
|
|
||||||
|
# Пример использования с кастомными ГОСТ настройками:
|
||||||
|
"""
|
||||||
|
settings = DocumentSettings()
|
||||||
|
settings.font_name = "Times New Roman"
|
||||||
|
settings.font_size = 14
|
||||||
|
settings.heading1_font_size = 16
|
||||||
|
settings.heading2_font_size = 14
|
||||||
|
settings.line_spacing = 1.5
|
||||||
|
settings.margin_left = 3.0 # для переплета
|
||||||
|
settings.auto_numbering_headings = True
|
||||||
|
settings.numbering_format = "decimal" # 1.1.1 формат
|
||||||
|
settings.page_numbering = True
|
||||||
|
settings.page_number_position = "bottom_center"
|
||||||
|
|
||||||
|
converter = MarkdownToDocxConverter(settings)
|
||||||
|
converter.convert("dissertation.md", "dissertation_gost.docx")
|
||||||
|
"""
|
||||||
|
|
@ -1,44 +0,0 @@
|
||||||
[build-system]
|
|
||||||
requires = ["hatchling>=1.24"]
|
|
||||||
build-backend = "hatchling.build"
|
|
||||||
|
|
||||||
[project]
|
|
||||||
name = "md2gost"
|
|
||||||
dynamic = ["version"]
|
|
||||||
description = "Markdown to DOCX formatted per GOST 7.32-2017 (Russian standard for reports)"
|
|
||||||
readme = "README.en.md"
|
|
||||||
license = "MIT"
|
|
||||||
license-files = ["LICENSE"]
|
|
||||||
authors = [{ name = "Egor Deev", email = "egor@deev.space" }]
|
|
||||||
requires-python = ">=3.9"
|
|
||||||
dependencies = ["python-docx>=1.1"]
|
|
||||||
keywords = ["markdown", "docx", "gost", "word", "report", "converter"]
|
|
||||||
classifiers = [
|
|
||||||
"Programming Language :: Python :: 3",
|
|
||||||
"Operating System :: OS Independent",
|
|
||||||
"Environment :: Console",
|
|
||||||
"Natural Language :: Russian",
|
|
||||||
"Topic :: Office/Business :: Office Suites",
|
|
||||||
"Topic :: Text Processing :: Markup :: Markdown",
|
|
||||||
]
|
|
||||||
|
|
||||||
[project.urls]
|
|
||||||
Homepage = "https://github.com/EDeev/my_converterbot"
|
|
||||||
Issues = "https://github.com/EDeev/my_converterbot/issues"
|
|
||||||
Bot = "https://t.me/my_convbot"
|
|
||||||
|
|
||||||
[project.scripts]
|
|
||||||
md2gost = "md2gost.cli:main"
|
|
||||||
|
|
||||||
[tool.hatch.version]
|
|
||||||
path = "md2gost/__init__.py"
|
|
||||||
|
|
||||||
[tool.hatch.build.targets.wheel]
|
|
||||||
packages = ["md2gost"]
|
|
||||||
|
|
||||||
[tool.hatch.build.targets.sdist]
|
|
||||||
include = ["md2gost", "tests/test_md2gost.py", "README.md", "README.en.md", "LICENSE"]
|
|
||||||
|
|
||||||
[tool.ruff]
|
|
||||||
target-version = "py39"
|
|
||||||
line-length = 120
|
|
||||||
|
|
@ -1,4 +1,3 @@
|
||||||
import argparse
|
|
||||||
import os
|
import os
|
||||||
|
|
||||||
IGNORE_PATTERNS = {
|
IGNORE_PATTERNS = {
|
||||||
|
|
@ -101,11 +100,13 @@ def process_single_file(relative_path, file_path):
|
||||||
|
|
||||||
file_ext = os.path.splitext(relative_path)[1].lower()
|
file_ext = os.path.splitext(relative_path)[1].lower()
|
||||||
|
|
||||||
# Обнаружение двоичных файлов (вместо изображений раньше выводилась ссылка-заготовка
|
# Обнаружение двоичных файлов и генерация URL-адресов
|
||||||
# https://raw.githubusercontent.com/.../ — она никуда не вела)
|
|
||||||
if file_ext in BINARY_EXTENSIONS or is_likely_binary(file_path):
|
if file_ext in BINARY_EXTENSIONS or is_likely_binary(file_path):
|
||||||
if file_ext in {'.png', '.jpg', '.jpeg', '.gif', '.svg', '.ico', '.webp', '.bmp'}:
|
# GitHub raw URL
|
||||||
content_lines.append("[Image - content not displayed]")
|
if file_ext in {'.png', '.jpg', '.jpeg', '.gif', '.svg', '.ico'}:
|
||||||
|
# Структура URL - настраивается на основе фактического хранилища
|
||||||
|
github_url = f"https://raw.githubusercontent.com/.../{relative_path.replace(os.sep, '/')}"
|
||||||
|
content_lines.append(github_url)
|
||||||
else:
|
else:
|
||||||
content_lines.append("[Binary file - content not displayed]")
|
content_lines.append("[Binary file - content not displayed]")
|
||||||
else:
|
else:
|
||||||
|
|
@ -140,22 +141,25 @@ def is_likely_binary(file_path):
|
||||||
chunk = f.read(8192)
|
chunk = f.read(8192)
|
||||||
# Обнаружение нулевого байта - надежный бинарный индикатор
|
# Обнаружение нулевого байта - надежный бинарный индикатор
|
||||||
return b'\x00' in chunk
|
return b'\x00' in chunk
|
||||||
except OSError:
|
except:
|
||||||
return True
|
return True
|
||||||
|
|
||||||
|
|
||||||
def main(argv=None):
|
|
||||||
parser = argparse.ArgumentParser(description="Дерево каталогов проекта и содержимое текстовых файлов в один .txt")
|
|
||||||
parser.add_argument("path", help="папка проекта")
|
|
||||||
parser.add_argument("-o", "--output", help="куда сохранить (по умолчанию <папка>_rep.txt)")
|
|
||||||
args = parser.parse_args(argv)
|
|
||||||
|
|
||||||
project_path = os.path.abspath(args.path)
|
|
||||||
output = args.output or os.path.basename(project_path.rstrip(os.sep)) + "_rep.txt"
|
|
||||||
with open(output, "w", encoding="utf-8") as f:
|
|
||||||
f.write(generate_complete_project_structure(project_path))
|
|
||||||
print(output)
|
|
||||||
|
|
||||||
|
|
||||||
if __name__ == "__main__":
|
if __name__ == "__main__":
|
||||||
main()
|
# Конфигурация: измените путь к целевому каталогу проекта
|
||||||
|
project_path = r"D:\Programs\GitHub\deev.space\static"
|
||||||
|
# project_path = r"D:/Programs/GitHub/openoffice"
|
||||||
|
# project_path = "."
|
||||||
|
|
||||||
|
print("Приступаем к формированию комплексной структуры проекта...")
|
||||||
|
tree_output = generate_complete_project_structure(project_path)
|
||||||
|
|
||||||
|
output_filename = project_path.split('\\')[-1] + "_rep.txt"
|
||||||
|
try:
|
||||||
|
with open(output_filename, "w", encoding="utf-8") as f:
|
||||||
|
f.write(tree_output)
|
||||||
|
print(f"\nПолная проектная документация, сохраненная в: {output_filename}")
|
||||||
|
except Exception as e:
|
||||||
|
print(f"Предупреждение: Не удалось сохранить файл - {e}")
|
||||||
|
|
||||||
|
print("Формирование структуры проекта успешно завершено!")
|
||||||
|
|
@ -1,4 +0,0 @@
|
||||||
-r requirements.txt
|
|
||||||
pytest==8.4.2
|
|
||||||
ruff==0.14.0
|
|
||||||
build==1.3.0
|
|
||||||
|
|
@ -1,2 +1,5 @@
|
||||||
aiogram==3.23.0
|
aiogram==3.13.1
|
||||||
python-docx==1.2.0
|
python-docx==1.1.2
|
||||||
|
aiohttp>=3.9.0
|
||||||
|
aiofiles>=23.0.0
|
||||||
|
certifi>=2023.0.0
|
||||||
|
|
|
||||||
|
|
@ -1,4 +0,0 @@
|
||||||
import os
|
|
||||||
import sys
|
|
||||||
|
|
||||||
sys.path.insert(0, os.path.join(os.path.dirname(__file__), ".."))
|
|
||||||
|
|
@ -1,41 +0,0 @@
|
||||||
import io
|
|
||||||
import os
|
|
||||||
import zipfile
|
|
||||||
|
|
||||||
import pytest
|
|
||||||
|
|
||||||
os.environ.setdefault("BOT_TOKEN", "123456:TEST")
|
|
||||||
|
|
||||||
import bot # noqa: E402
|
|
||||||
from rep_to_txt import generate_complete_project_structure # noqa: E402
|
|
||||||
|
|
||||||
|
|
||||||
def test_zip_bomb_is_rejected(tmp_path, monkeypatch):
|
|
||||||
monkeypatch.setattr(bot, "MAX_UNPACKED_SIZE", 1000)
|
|
||||||
archive = tmp_path / "a.zip"
|
|
||||||
with zipfile.ZipFile(archive, "w", zipfile.ZIP_DEFLATED) as z:
|
|
||||||
z.writestr("big.txt", "0" * 10_000)
|
|
||||||
with pytest.raises(bot.ArchiveTooLarge):
|
|
||||||
bot.analyze_archive(str(archive), str(tmp_path))
|
|
||||||
|
|
||||||
|
|
||||||
def test_archive_structure(tmp_path):
|
|
||||||
archive = tmp_path / "p.zip"
|
|
||||||
with zipfile.ZipFile(archive, "w") as z:
|
|
||||||
z.writestr("proj/main.py", "print(1)\n")
|
|
||||||
z.writestr("proj/img.png", b"\x89PNG\x00")
|
|
||||||
z.writestr("proj/node_modules/x.js", "ignored")
|
|
||||||
text = open(bot.analyze_archive(str(archive), str(tmp_path)), encoding="utf-8").read()
|
|
||||||
assert "main.py" in text and " 1 | print(1)" in text
|
|
||||||
assert "[Image - content not displayed]" in text and "node_modules" not in text
|
|
||||||
|
|
||||||
|
|
||||||
def test_structure_of_missing_path():
|
|
||||||
assert generate_complete_project_structure("/no/such/dir").startswith("Error")
|
|
||||||
|
|
||||||
|
|
||||||
def test_docx_conversion_in_bot(tmp_path):
|
|
||||||
md = tmp_path / "a.md"
|
|
||||||
md.write_text("# Тест\n", encoding="utf-8")
|
|
||||||
out = bot.convert_md_to_docx(str(md), str(tmp_path))
|
|
||||||
assert zipfile.is_zipfile(io.BytesIO(open(out, "rb").read()))
|
|
||||||
|
|
@ -1,105 +0,0 @@
|
||||||
import zipfile
|
|
||||||
|
|
||||||
from docx import Document
|
|
||||||
|
|
||||||
from md2gost import DocumentSettings, MarkdownToDocxConverter
|
|
||||||
from md2gost.cli import main as cli_main
|
|
||||||
|
|
||||||
SAMPLE = """# Отчёт о практике
|
|
||||||
|
|
||||||
## Введение
|
|
||||||
|
|
||||||
Абзац с **жирным**, *курсивом*, `кодом` и сноской[^1].
|
|
||||||
|
|
||||||
### Цели
|
|
||||||
|
|
||||||
- Первый пункт
|
|
||||||
- Второй пункт
|
|
||||||
- Вложенный пункт
|
|
||||||
|
|
||||||
1. Раз
|
|
||||||
2. Два
|
|
||||||
|
|
||||||
Второй список:
|
|
||||||
|
|
||||||
1. Снова один
|
|
||||||
2. Снова два
|
|
||||||
|
|
||||||
| Параметр | Значение |
|
|
||||||
|---|---|
|
|
||||||
| A | 1 |
|
|
||||||
|
|
||||||
Строка с | вертикальной чертой, но не таблица.
|
|
||||||
|
|
||||||
## Список литературы
|
|
||||||
|
|
||||||
1. Иванов И. И. Книга. — М., 2020.
|
|
||||||
2. Петров П. П. Статья. — СПб., 2021.
|
|
||||||
|
|
||||||
[^1]: Текст сноски.
|
|
||||||
"""
|
|
||||||
|
|
||||||
|
|
||||||
def convert(tmp_path, text=SAMPLE, **options):
|
|
||||||
src = tmp_path / "in.md"
|
|
||||||
src.write_text(text, encoding="utf-8")
|
|
||||||
settings = DocumentSettings()
|
|
||||||
settings.auto_numbering_headings = True
|
|
||||||
for key, value in options.items():
|
|
||||||
setattr(settings, key, value)
|
|
||||||
out = tmp_path / "out.docx"
|
|
||||||
MarkdownToDocxConverter(settings).convert(str(src), str(out))
|
|
||||||
return out
|
|
||||||
|
|
||||||
|
|
||||||
def texts(path):
|
|
||||||
return [p.text for p in Document(str(path)).paragraphs if p.text.strip()]
|
|
||||||
|
|
||||||
|
|
||||||
def test_page_number_field_and_title_page(tmp_path):
|
|
||||||
out = convert(tmp_path)
|
|
||||||
with zipfile.ZipFile(out) as z:
|
|
||||||
footers = [z.read(n).decode() for n in z.namelist() if n.startswith("word/footer")]
|
|
||||||
document = z.read("word/document.xml").decode()
|
|
||||||
assert any("PAGE" in f for f in footers)
|
|
||||||
assert "<w:titlePg/>" in document
|
|
||||||
|
|
||||||
|
|
||||||
def test_heading_font_is_not_theme_font(tmp_path):
|
|
||||||
out = convert(tmp_path)
|
|
||||||
with zipfile.ZipFile(out) as z:
|
|
||||||
styles = z.read("word/styles.xml").decode()
|
|
||||||
heading = styles[styles.index('w:styleId="Heading1"'):]
|
|
||||||
heading = heading[:heading.index("</w:style>")]
|
|
||||||
assert "asciiTheme" not in heading and 'w:ascii="Times New Roman"' in heading
|
|
||||||
|
|
||||||
|
|
||||||
def test_lists_have_single_dash_nesting_and_restart(tmp_path):
|
|
||||||
lines = texts(convert(tmp_path))
|
|
||||||
assert "– Первый пункт" in lines
|
|
||||||
nested = next(p for p in Document(str(convert(tmp_path))).paragraphs if p.text == "– Вложенный пункт")
|
|
||||||
assert nested.paragraph_format.left_indent.cm > 0
|
|
||||||
assert lines.count("1) Раз") == 1 and "1) Снова один" in lines
|
|
||||||
|
|
||||||
|
|
||||||
def test_structural_headings_are_not_numbered(tmp_path):
|
|
||||||
lines = texts(convert(tmp_path))
|
|
||||||
assert "ВВЕДЕНИЕ" in lines and "СПИСОК ЛИТЕРАТУРЫ" in lines
|
|
||||||
assert "1.1. Цели" in lines # нумерация разделов идёт мимо «Введения»
|
|
||||||
assert "1. Иванов И. И. Книга. — М., 2020." in lines
|
|
||||||
|
|
||||||
|
|
||||||
def test_table_and_pipe_paragraph(tmp_path):
|
|
||||||
out = convert(tmp_path)
|
|
||||||
doc = Document(str(out))
|
|
||||||
assert len(doc.tables) == 1 and doc.tables[0].cell(1, 1).text == "1"
|
|
||||||
assert "Строка с | вертикальной чертой, но не таблица." in texts(out)
|
|
||||||
|
|
||||||
|
|
||||||
def test_cli(tmp_path, capsys):
|
|
||||||
src = tmp_path / "doc.md"
|
|
||||||
src.write_text("# Заголовок\n\nТекст\n", encoding="utf-8")
|
|
||||||
assert cli_main([str(src), "--no-heading-numbers"]) == 0
|
|
||||||
out = tmp_path / "doc.docx"
|
|
||||||
assert out.exists() and "Заголовок" in texts(out)
|
|
||||||
assert cli_main([str(tmp_path / "nope.md")]) == 1
|
|
||||||
Loading…
Add table
Reference in a new issue